Agregátor RSS
Why Urgent Security Fixes Aren't Fixed. Observe, Prove, Act, Confirm Gets Them Moving
The alert is critical. The fix is known. And the ticket sits in a queue for days. Security teams understand the risk, but the people who keep applications available need proof that the change won’t break anything.
Their concerns are practical. An IPS protection could block legitimate traffic. A configuration change could interrupt a service. An endpoint policy could affect an application [email protected]
Kategorie: Hacking & Security
Microsoft nasadil tempo. Windows 11 26H2 jsou už dostupné pro každého
Microsoft po měsíci od uvedení Windows 11 26H2 dosáhl milníku v distribuci. • Nové vydání operačního systému už nabízí na všech kompatibilních počítačích. • Instalaci ale ještě nevynucuje, zahájit ji můžete ve službě Windows Update.
Kategorie: IT News
British intelligence agency misplaced 'thousands' of storage devices, years later still can't say how many
Thousands of GCHQ storage drives containing sensitive data have been lost for years, and the British signals intelligence agency still cannot explain where they are. According to the Investigatory Powers Commissioner’s Office’s (IPCO) annual report, the missing storage drives have been known to officials for years, and may contain data related to the Investigatory Powers Act (IPA). "I remain concerned that GCHQ has not yet established a sufficiently clear understanding of the scale, location, and recoverability of lost removable media that may contain IPA-related data, notwithstanding that the underlying issues were first drawn to my attention several years ago," wrote investigatory powers commissioner Lord Brian Leveson. "While I recognize the technical and practical challenges involved, the passage of time without a comprehensive account heightens the importance of sustained senior focus and assured remediation. Given the potential sensitivity of the material involved, I will continue to monitor progress closely.” Described as "a very significant number," the report notes that GCHQ has scoped the maximum number of potentially lost drives, but is unaware of the exact scale of the issue. The agency has embarked on "a program of further work" to locate as many of the lost devices as possible, which includes implementing an automated asset-tracking system by the end of the year. After this is up and running, it said it will be able to provide a more precise number of lost drives. A GCHQ spokesperson told The Register: "As IPCO have reported, our management system for removable media was previously not sufficiently robust to effectively track the items that were registered for use. IPCO are right to note the flaws in the data the system produced, and we have taken action against all their recommendations. "We recognize the importance of security of removable media in our systems, and have a range of measures to mitigate the risks posed by these items. The findings in the report have been addressed comprehensively, and all necessary steps to correct this issue have been taken." Peter Sommer, digital forensics expert and visiting professor at de Montfort and Birmingham City universities, told us: "Bearing in mind the sort of highly sensitive data collected and processed by GCHQ IPCO is right to be very concerned, the more so as the issue is already several years old. Vast quantities of data can be stored on the cheapest lowest cost hard disks and cards. At a much more modest level as an expert witness I know how important it is to keep careful track of the data entrusted to me." Losing important devices is not an achievement that's exclusive to GCHQ. Myriad stories like this have emerged from all corners of the public sector over the years, such as the British Minidstry of Defence misplacing USB drives containing secret information in the mid-noughties, civil servants routinely losing their BlackBerry handsets, and UK police losing thousands of devices, too. The missing storage drives comprise just one of the agency's various transgressions highlighted by IPCO in its report. There are also "significant concerns" over the lax safeguards used to restrict the UK's overseas partners when accessing bulk-intercepted data collected by GCHQ. IPCO was satisfied at how GCHQ ensured its own analysts remained compliant with safeguards around accessing confidential material related to journalism, journalistic sources, and privileged legal information. However, there were concerns around how these same safeguards were applied to its international partners, which have access to its so-called bulk data interception "product." The report notes that most partners were properly restricted from accessing such material, although an internal probe found that there were inadequate arrangements in respect to one partner and their access to journalistic material. Both GCHQ and the overseas agency committed to rectifying the situation. GCHQ was also questioned after a software bug in a web app "used by a relatively small section of the public" misidentified individuals thought to be participating in terrorist activities. The agency identified and reported the flaw in the software, which it used for "target discovery work," and although it only affected a small number of individuals, the errors led to five port stops made under the Terrorism Act and caused "serious prejudice" to the victims. A port stop, for the uninitiated, involves law enforcement detaining a suspect at a UK port, airport, train station, or within one mile of the Northern Ireland border, and can be carried out without suspicion. Once detained, individuals have a legal responsibility to provide passwords to their electronic devices, which can be seized for up to seven days, and in some cases have their biometric markers taken. Failure to comply can lead to a three-month prison term. IPCO ruled, however, that there was ultimately no error made as defined by the IPA. “This is because the activity was lawfully authorised under an interception warrant and the adoption of an unintentionally and unforeseeably imperfect target discovery methodology did not constitute such an error,” the report stated. Despite the agency’s vast technical expertise, IPCO said that the issue affecting the software was not foreseeable. GCHQ was not the only offender among the UK intelligence community (UKIC), with MI5's mishandling of the infamous Agent X case taking center stage in the report. Agent X was an anonymous MI5 informant whose real identity has never been publicly released. A secret inquiry by IPCO as well as the report revealed that MI5 managed Agent X despite knowing he was a violent misogynist obsessed with extreme violence. Lord Leveson said "the case of Agent X is as serious as anything I have dealt with as Commissioner," after MI5 gave false evidence to the High Court and Investigatory Powers Tribunal to protect a foreign neo-Nazi informant who was under police investigation for abusing his partner, referred to publicly as "Beth." ®
Kategorie: Viry a Červi
Microsoft finally fixes VPN issues caused by September updates
Microsoft has resolved Always On VPN connection failures triggered after installing the September 2026 Windows 11 security updates. [...]
Kategorie: Hacking & Security
Don’t trust AI to keep your secrets
We talk to chatbots as if those conversations are private. But are they?
Most people are confused. A survey commissioned by DuckDuckGo and published in August asked 1,944 American adults about chatbot privacy, and more than half (53%) did not know whether their conversations were being used to train the bots. (They are.)
Only a quarter of respondents knew that chatbot conversations can be subpoenaed. (They can.)
Among self-described AI enthusiasts, 56% said they had confided to a chatbot something they had never told a close friend, parent, colleague, doctor, or therapist.
That’s especially true on Character.AI, a chatbot service where users can chat and form “relationships” with customizable characters, including ones they create and share with the community. On Character.AI, some users chat about thoughts of suicide and self-harm, and they surrender private details like mental health disclosures, ages, private chats and voice calls, deep fears, and relationship struggles.
Character.AI was all fun and games until earlier this month, when the company filed for bankruptcy and opened a court-supervised sale of its assets.
Nobody knows who will end up with the company, or how much of the data on its millions of account holders will be sold as well.
The most valuable asset for sale by the company may be its LLM, which has been substantially trained by users as they build and interact with characters.
Legally, a company can sell personal data about its users if its privacy policy permits the transfer. Character.AI’s privacy policy is spectacularly vague. It says the company may disclose “certain information” in the company’s sale. Nobody knows what that means.
The US Trustee Office, an arm of the Justice Department, wants the judge to appoint a consumer privacy ombudsman to advise the court on user privacy. The judge could restrict the sale of company “records,” including user data.
But here’s the part most people don’t understand: The Bankruptcy Code has no provision specifically addressing trained models. The legal status of LLMs and their training data has yet to be settled in law. That means it’s entirely possible that the data users fed into Character.AI will be sold to whoever buys it.
Character.AI is just one handy example. The larger risk is all the other AI companies out there.
More surprising facts about LLM privacyThe core question is this: Can personal or proprietary information shared in a chat end up inside an LLM, where anyone might coax it out?
The answer is a resounding “uh, maybe.”
First of all, it depends on the AI chatbot service. The companies vary wildly in how they handle chat data, and the differences boil down to four questions: whether training on chats is on by default, whether human reviewers read them, how long they are kept, and whether they feed advertising.
Major chatbot companies generally try to reassure users about privacy. They publish privacy controls, but their own policies admit that consumer chats may be used for training by default, read by human reviewers, or both, and the fine print shifts from company to company.
Tellingly, some of them offer enterprise or business accounts that handle chat sessions privately. For example, they don’t use chat sessions in training data. That business accounts get extra privacy features sounds to me like an admission that individual accounts aren’t private.
Some companies, such as OpenAI, let users opt out of having their chats tossed into the training data. But OpenAI’s help documentation says that turning off training does not delete the chats themselves.
There are three main ways chatbot user data can be exposed. The first is bugs. In March 2023, a bug lurking in an open-source library called “redis-py” let some ChatGPT users see other users’ chat titles and, possibly, the first message of new conversations. More than 1% of ChatGPT Plus subscribers active in a nine-hour window may have had their payment details exposed to other users: names, email addresses, payment addresses, card types, the last four digits of card numbers and expiration dates.
The second is sharing. Some chatbots offer sharing features, and those features can publish chats to the world, whether on purpose or by accident. Once these sessions are posted, search engines are likely to gobble them up and make them searchable. In 2025, Forbes reported that Google’s results showed more than 370,000 Grok conversations after users clicked “share,” and shared ChatGPT chats turned up in search results until OpenAI killed the option.
The third is the absorption of chat sessions into the training data.
Let’s take one simple example: an email address. People often paste in emails so that a chatbot will write the reply. These emails often contain names, email addresses and other information in the header, the signature, or both.
The question I often ponder is this: If emails addressed to one person get pasted into chats hundreds of times, can a stranger ask the chatbot for that person’s address and actually get it back?
In a 2022 study, GPT-Neo models given only a person’s name recovered the right email address no more than 1.24% of the time, but with the domain supplied, the rate climbed to 16.55%, and to 37.06% after five examples. Other factors, including how often an address appeared in the training data and whether surrounding email text came along with it, pushed the rate higher.
Deleting chat records isn’t a remedy, either. Several state attorneys general said deleting chat records may not undo their influence on trained models. And Common Sense Media’s Robbie Torney claimed that exporting or deleting your data “may not mean that that data is gone from model training.”
Note that people not only enter personal information about themselves during AI chats, but about their co-workers, friends, and relatives.
The main thing standing between your secrets and the world is company practice. We depend on the AI companies to keep our information private.
So what happens when those companies sell their assets?
When AI bubbles burstOnline chatter about the “AI bubble” bursting is pretty much constant.
In China, the AI bubble has already burst, according to Reuters. Over the past few months, Chinese AI stocks have been pummeled.
Reuters reported that Shanghai’s STAR50 index of tech stocks fell 40% from its July high in under four months, erasing about $480 billion in market value, and that the broader CSI300 is down about 20% from its June highs.
It’s not a total collapse, but it does put pressure on US stock prices and also provides an incentive to transfer ownership through sales or mergers (though this hasn’t happened in China yet).
Still, the future is unknowable. Which AI companies will go bust as Character.AI did, get sold off, or get hacked?
As for the chatbots themselves, their inner workings are also unknowable.
That’s why we should all listen to the most paranoid amongst us, and never put sensitive information into chatbots. We just can’t trust AI to keep our secrets.
Kategorie: Hacking & Security
Kim Čong-un se fotil s drony a chce chudou Koreu proměnit v bezpilotní velmoc
V létě 2023 Severokorejci poprvé předvedli velký dron, který jako by z oka vypadl ikonickému americkému letounu MQ-9 Reaper. Říkají mu 샛별-9 (Saetbyol-9), tedy Ranní hvězda 9.
Podle odhadů až devítimetrové monstrum s rozpětím křídel okolo dvaceti metrů nicméně tehdy vezli pouze na korbě vojenského ...
Kategorie: IT News
Syrian Hacker Behind Fake Tweet That Triggered $136 Billion Market Drop Gets 42 Months in Prison
Ahmad Umar Agha, a Syrian Electronic Army hacker known online as "Th3Pr0," has been sentenced by a U.S. federal court to 42 months in prison for his role in a hacking conspiracy that targeted Western news outlets.
The conspiracy was organized and led by members of former Syrian President Bashar al-Assad's inner circle, including the commander of Syria's General Intelligence Swati Khandelwalhttp://www.blogger.com/profile/[email protected]
Kategorie: Hacking & Security
Drupal warns of critical Commerce Core flaw exploited in attacks
Drupal warned admins to patch a critical access bypass vulnerability in the Commerce Core module that attackers are exploiting in the wild. [...]
Kategorie: Hacking & Security
Jak na bezpečné přetaktování procesorů AMD Ryzen. Průvodce krok za krokem
Přetaktování procesorů AMD lze udělat kompletně z prostředí operačního systému, zkušení uživatelé by však měli zavítat i do UEFI.
Kategorie: IT News
Filter generation in practice: from algorithms to LLMs
A modern organization protects its information systems with a whole suite of technologies that generate thousands of security alerts every day. Looking at these alerts in bulk, you’ll see that a significant share are false positives. Ideally, these alerts would be filtered out automatically so that analysts could focus on the ones that may point to a real incident. However, writing filters is a time-consuming task in itself. To create a correct filter, an analyst needs to:
- Review the logs
- Identify the source of the activity
- Define filtering boundaries
- Choose filtering criteria
- Write a rule
- Check that the filter is robust
This post looks at how filter creation itself can be automated to reduce analyst workload.
Filter validity criteriaIn the context of security alerts, a filter is a combination of event field values that marks a detection as a false positive and not worth the analyst’s attention. Filters can be generated for any combination of event fields, but not every combination yields a valid filter. That’s why we need to define validity criteria: conditions showing that a specific filter actually removes noise and doesn’t suppress useful alerts.
Detection rules in security systems typically contain a set of conditions, and each of them can generate an alert. A specific event triggers a given fragment of a detection rule. The set of events that a given fragment responds to is what we’ll call its context. A good filter should cover the entire context where possible, without going beyond it. Filters that are too broad or too narrow are useless. For example, a filter based solely on PowerShell would exclude too many events, including some that deserve the analyst’s attention. Most of the filtered events would also be unrelated to the rule in question. A filter on a specific ID, on the other hand, would cover only one event, which may never recur.
Problems in filter generationWe can run into a number of problems when creating filters. First, events often contain an excessive number of fields (around 400 on average), and most of them aren’t needed for filtering. At the same time, generating and ranking combinations of these fields is also fairly resource-intensive. So, the first step is to discard the irrelevant fields and keep only those worth using in the filter. For example, out of 400 fields in an event, four may be enough for filtering.
Another problem is string normalization. Field values (for example, the path to the same application on different systems) can vary depending on system settings, user folder names, and so on. For a filter to account for all these variations, the strings must be normalized. For file paths, in particular, you can replace the drive letter and user folders with standard environment variables and convert all paths to a single case.
Finally, if a filter completely mirrors the query of a detection rule, it effectively disables that rule. To fix this, remove the event fields used in the detection rule from the filter. For example, if a rule triggers on a file path, there are two ways to filter out unwanted alerts:
- In the filter, use fields other than the file path.
- Use a part of the file path that the rule doesn’t use. For example, for the rule file_path: ".../something.exe", you can set up a filter that excludes events with the user/unique_files/ directory in the file path.
Given the problems described above, automatically generating filters for security alerts should consist of the following steps:
- An analyst receives a security alert that they assess as a false positive and uses the filter generator.
- The generator takes the 400-field event from the alert, along with the rule that triggered on it, and determines the context.
- The generator selects the fields that are relevant to the filter.
- The generator normalizes the strings.
- The generator builds different combinations of the selected fields. To do this, we applied the FP-Growth (frequent pattern growth) algorithm to the context determined earlier. FP Growth builds a tree of frequently occurring items (fields) from a dataset (in our case, the context) and discards items that aren’t frequent enough. This reduces the number of combinations to check, which lowers the cost of finding the most relevant ones.
- The generator ranks the resulting combinations and offers the analyst the top three to choose from.
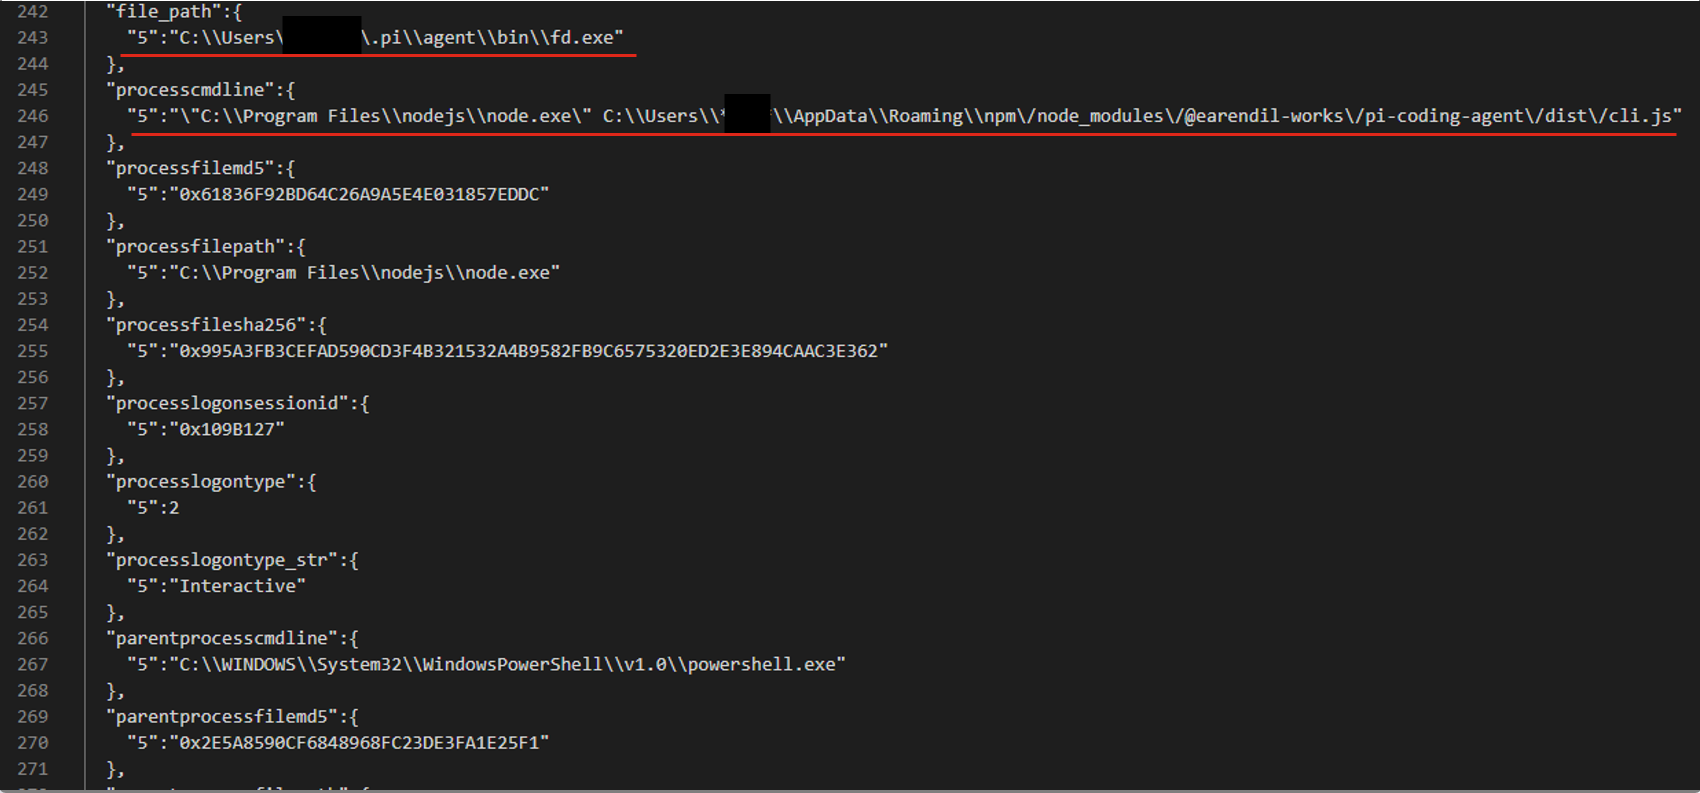
For example, consider an event described by the following JSON:
After generating and ranking the combinations, we got three filters based on file paths:
- processcmdline:("nodejs\\node.exe" AND "*****\\appdata\\roaming\\npm\/node_modules\/pi-coding-agent\/dist\/cli.js")
- file_path:"*****/.pi\\agent\\bin\\fd.exe"
- processcmdline: "programfiles\\nodejs\\node.exe"
The last filter turned out to be too broad, but the analyst marked the other two as valid.
Pros and cons of the algorithmic approachThe algorithmic approach to filter generation has several advantages. First, it’s simple and deterministic: the same alert always produces the same result. Second, it’s interpretable, meaning we can see why a given combination ranked near the top of the list and why a particular field didn’t make it into the list of candidate fields at all. Third, the stages of the process are independent of each other, so individual steps can be improved and tuned without the risk of breaking the algorithm elsewhere. Finally, it has no external dependencies or models, which makes it easy to deploy in any customer environment.
However, it also has drawbacks. The first is its dependence on context. If there’s no context for some reason — for example, the rule’s first-ever trigger — a filter can’t be created. The second problem is string normalization. There’s a high chance of running into atypical cases that the normalization rules don’t cover. Often such cases can’t be described correctly at all, because they contradict each other.
These problems can be solved with large language models (LLMs). When an LLM generates the filters, no context is needed, because the LLM doesn’t iterate over or rank combinations. The LLM also takes a more flexible approach to string normalization, including non-standard cases. That said, an LLM doesn’t have to be involved at every stage of the generation process. We decided to keep the algorithmic solution where it works well. For example, a simple algorithm selects suitable fields without errors, so we didn’t move this stage to the model.
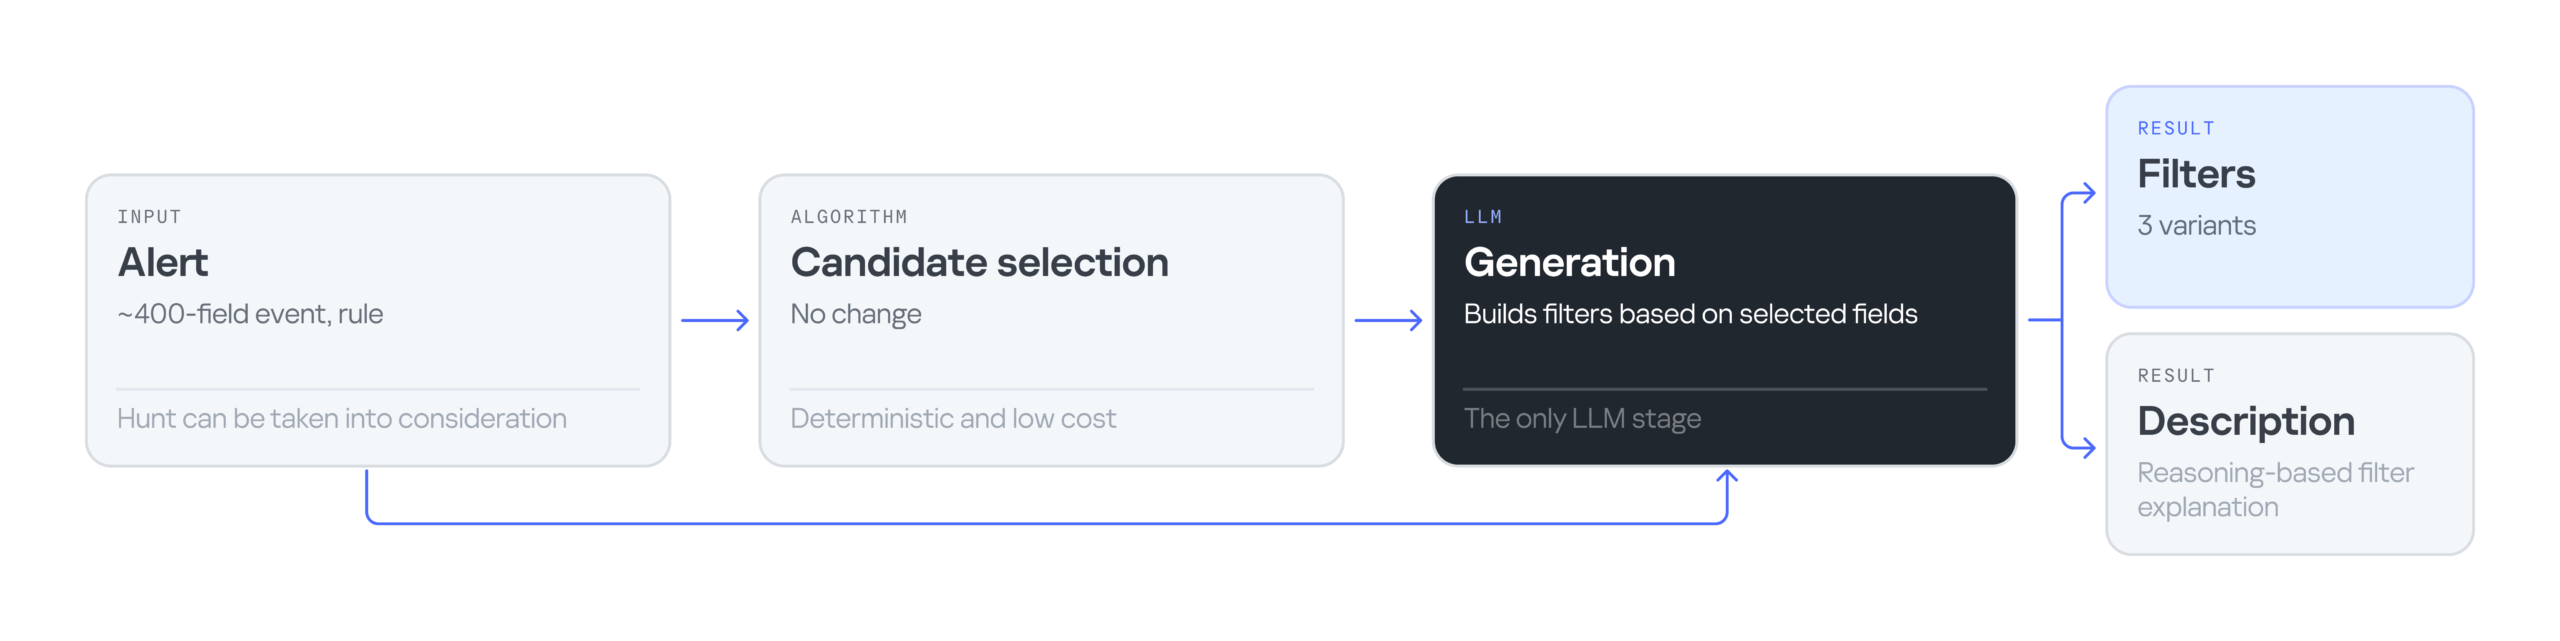
Filter generation with an LLMThe LLM-based filter generation looks like this:
The input is still an alert containing an event with 400 fields, plus the rule that triggered on that event. Then an algorithm selects the most suitable fields for the filter. Next, the LLM processes the input — the event, the selected fields, and the detection rule — and generates three filter options along with an explanation for them. The explanation helps the analyst understand why these particular filters were suggested and make an informed choice.
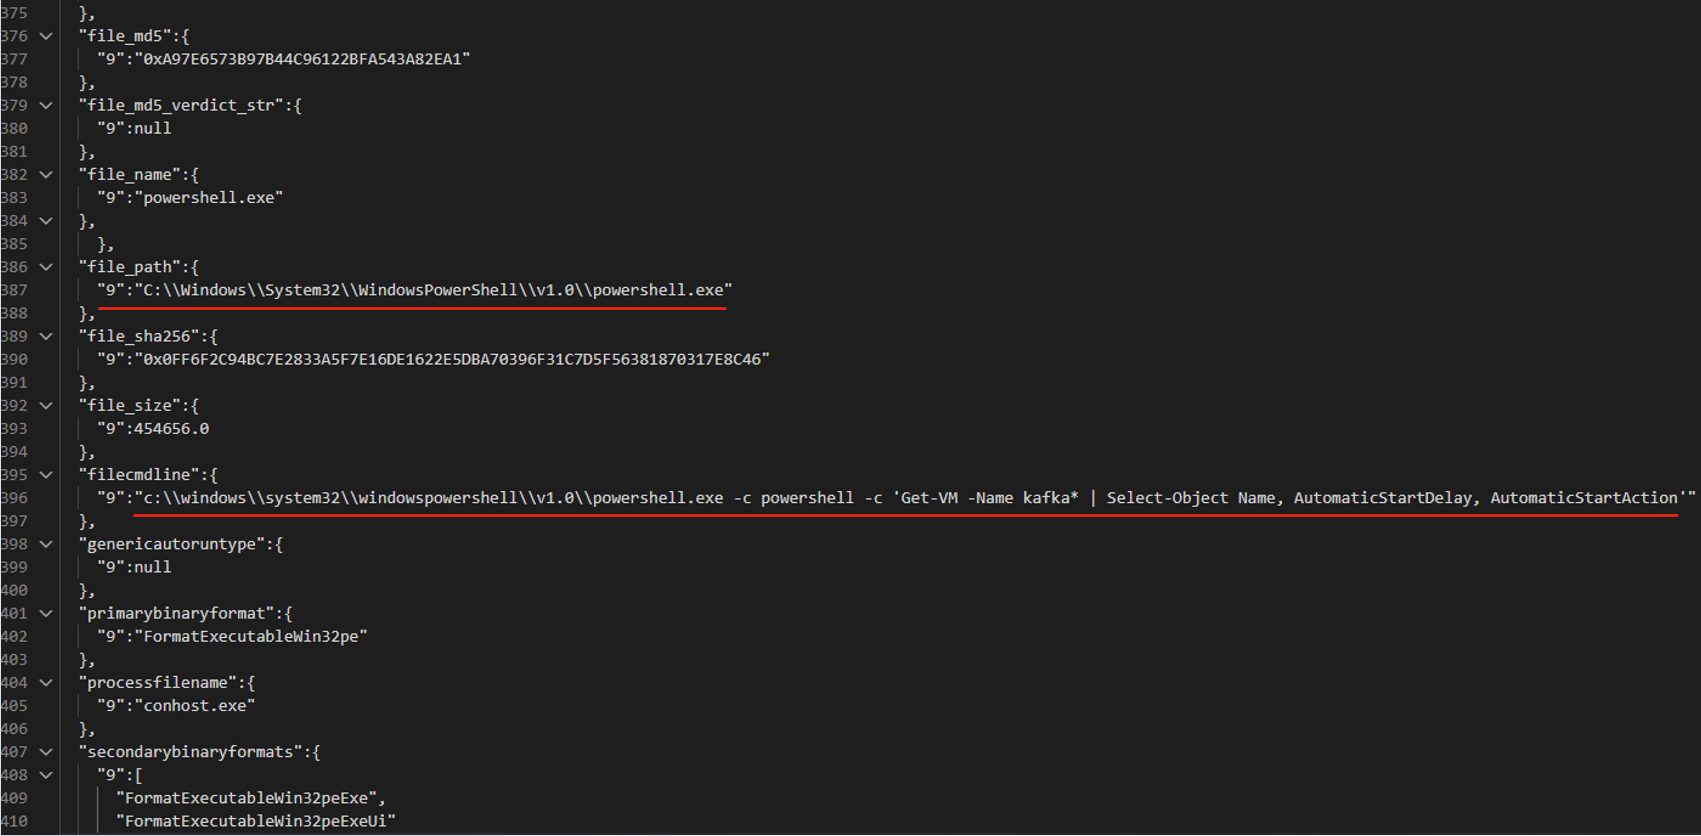
Consider the following event in JSON format:
The LLM suggested three filter options that all contain the same command line fragment:
- file_path: "\\WindowsPowerShell\\powershell.exe" AND filecmdline: "Get-VM -Name kafka\*"
- filecmdline: "Get-VM -Name kafka\*"
- filecmdline: "kafka*"
As in the previous example, two of the three output filters were valid. The last one was too broad to be usable. The analyst chose the first filter with minor edits:
file_path: "powershell.exe" AND filecmdline: "Get-VM -Name kafka\*" Pros and cons of generating filters with an LLMUsing an LLM solved the problems of purely algorithmic filter generation: dependence on context and errors in string normalization. However, the single-request approach had its own drawbacks. First, it had no output validation. The LLM returned filters as-is, with no syntax check and no way to correct errors. Second, unlike in the algorithmic version, all filter generation tasks were handled by a single system prompt. As a result, a minor fix in one place could break the logic in another.
Using multiple AI agentsTo address the problems of generating filters with a single model and a single system prompt, we tried distributing the tasks across different LLM agents. In this version, we brought in agents as early as the stage of selecting relevant fields. The chain includes four agents in total:
- Selector: selects the relevant fields.
- Generator: generates filters.
- Validator: evaluates the generated filters. If the filters are found to be invalid, it returns the task to the generator. If the selected fields are found to be irrelevant, it starts a new field selection cycle. If the filters pass validation, or the limit on regeneration attempts is reached, the valid filters (or the best ones available) are passed to the analyst.
- Commentator: analyzes the output filters and explains which field values were used and why.
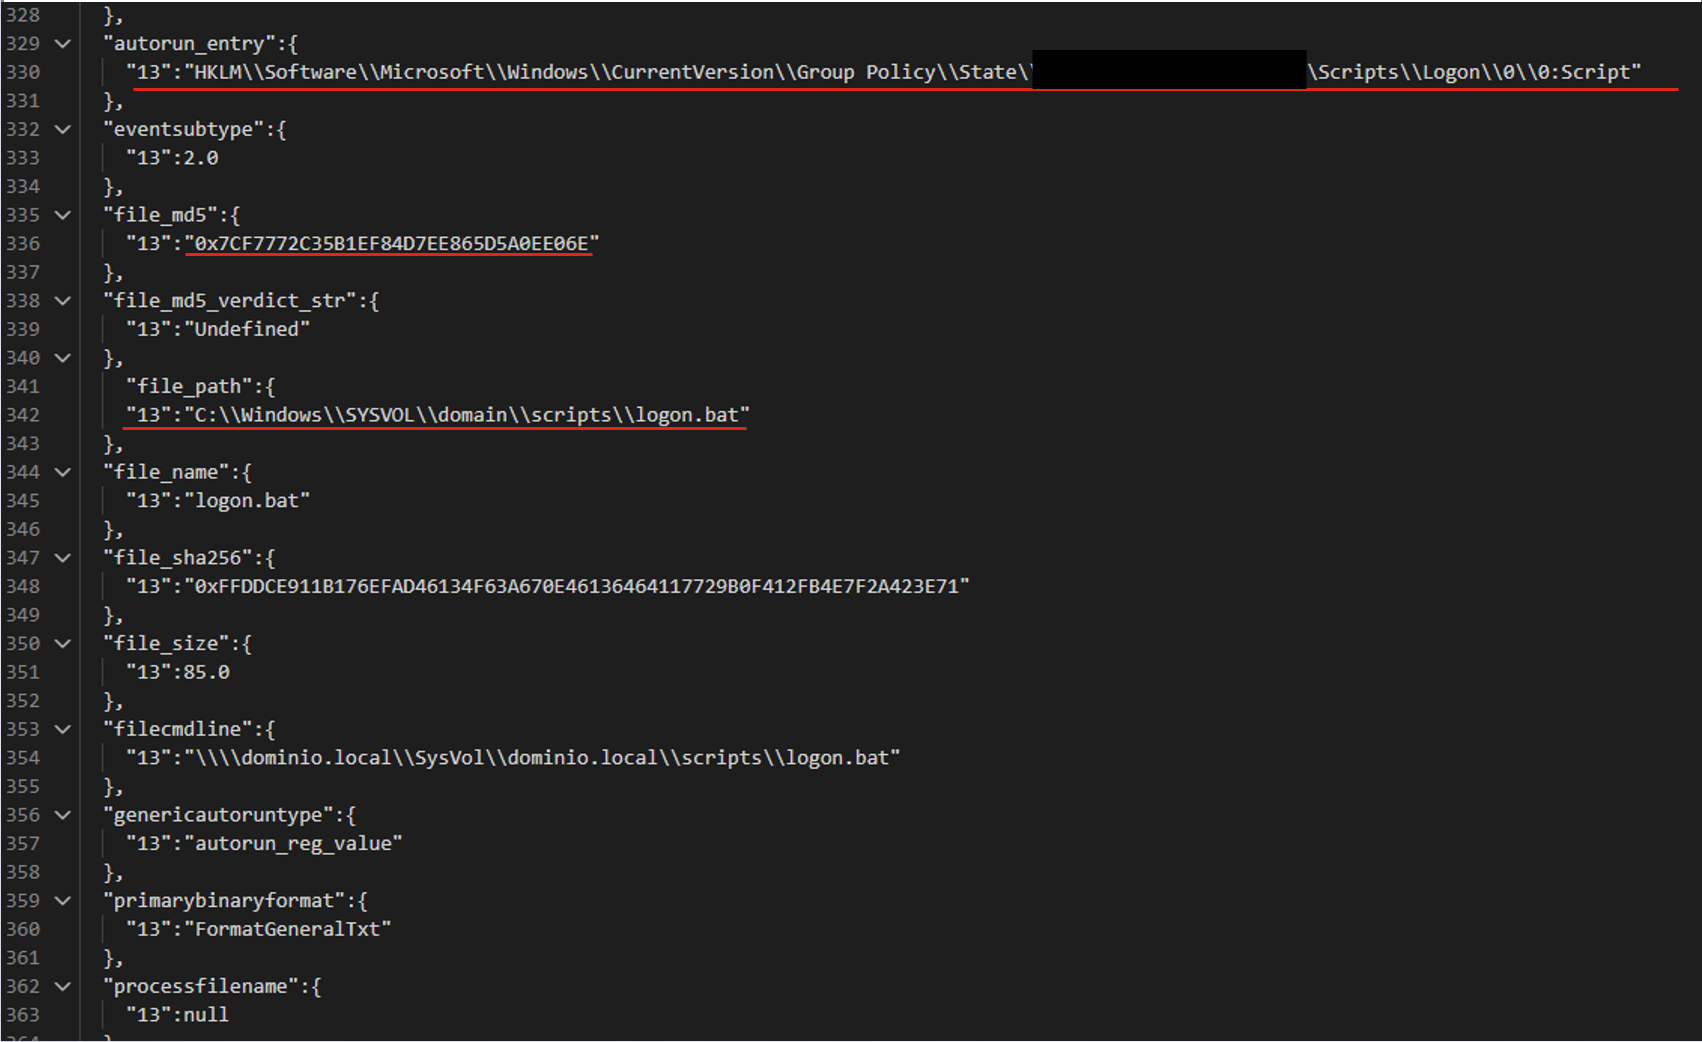
For the following JSON event, the agents produce three valid filters based on the file path.
The filters differ in the additional parameters that support the detection:
- file_path:"sysvol\\domain\\scripts\\logon.bat"
- file_path:"sysvol\\domain\\scripts\\logon.bat" AND file_md5:"0x7..6E"
- autorun_entry: "Group Policy\\State" AND file_path: "SYSVOL\\domain\\scripts\\logon.bat"
LLM agents give us a system that can validate and correct filters. Its modular architecture also lets us tune and improve different stages of generation independently. However, this approach makes more LLM calls than the previous ones, so the system is slower. It also depends on access to a model, which may not be available in the organization’s isolated environment.
Evaluating the filter generation systemTo evaluate how well the filter generation system works, we use two main metrics:
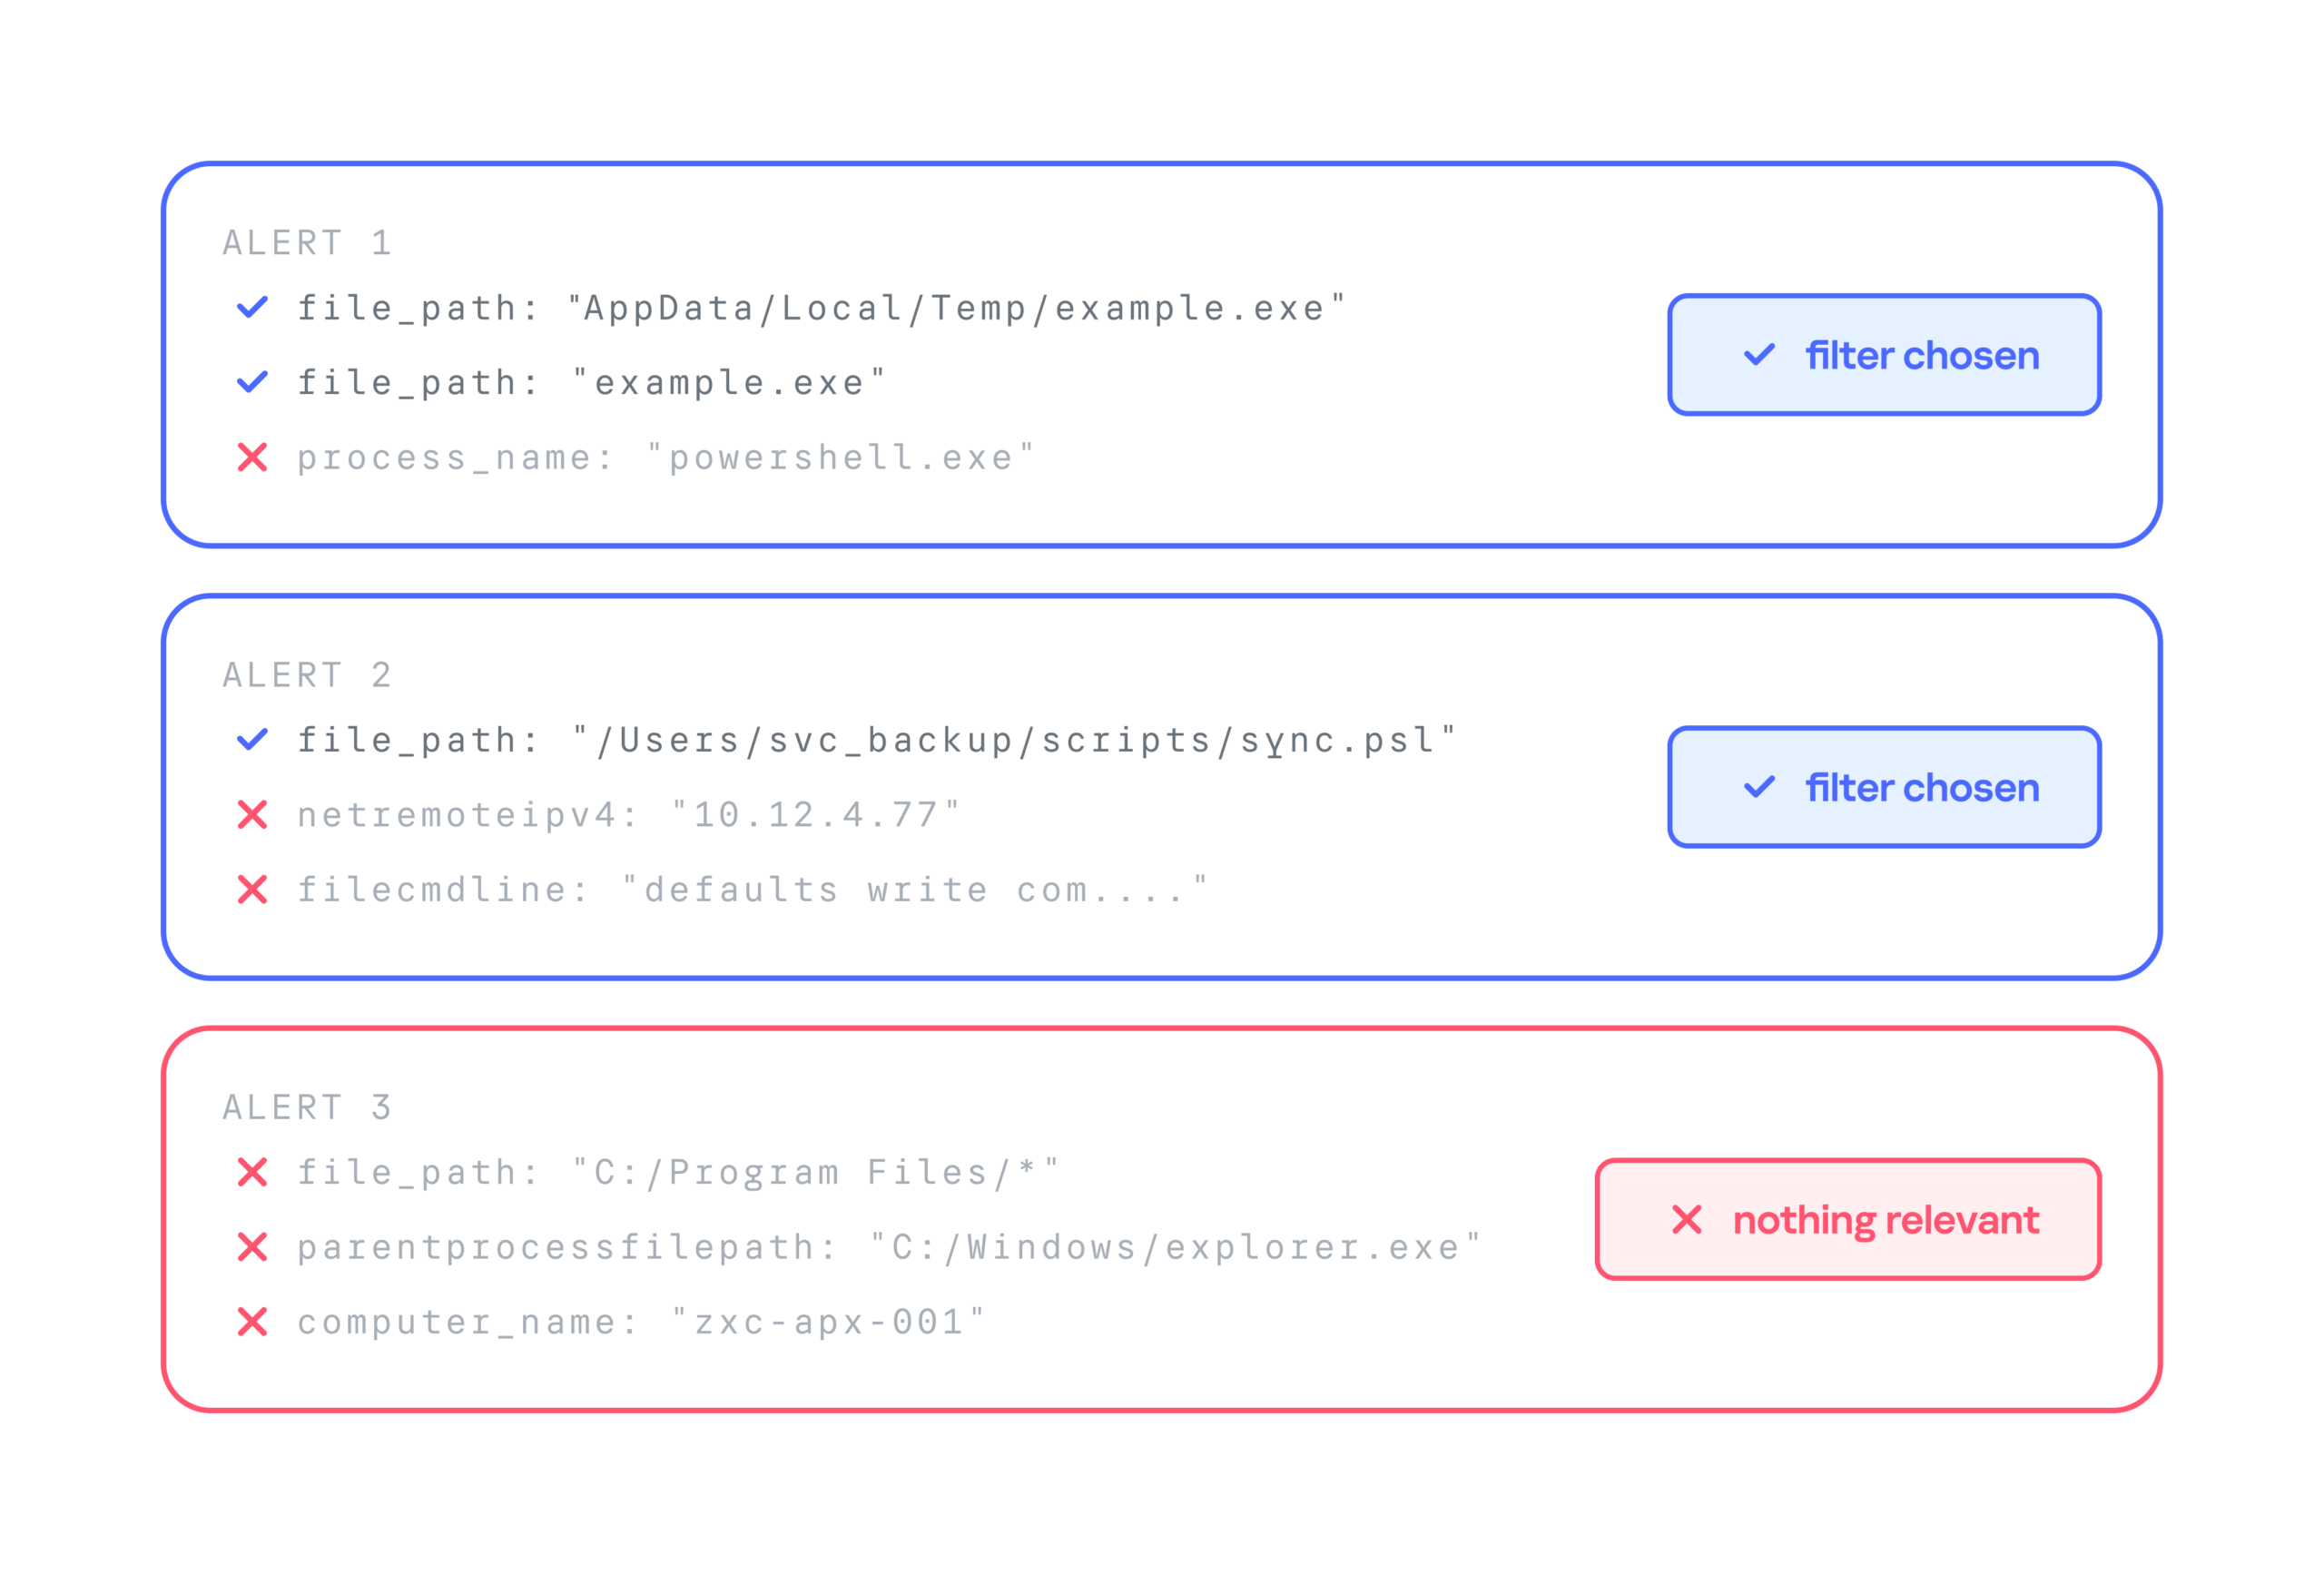
- Approval rate. For each security alert, the system suggests three filters. If the analyst selects at least one of them, we count the generation as successful. For example, in the case below, the approval rate is 2/3.
- False positive reduction rate (FP drop). This metric shows how much a filter helps reduce the number of false positives. It can only be measured over time, because we need to compare the number of false positive alerts received during a set period before and after the filter is deployed.
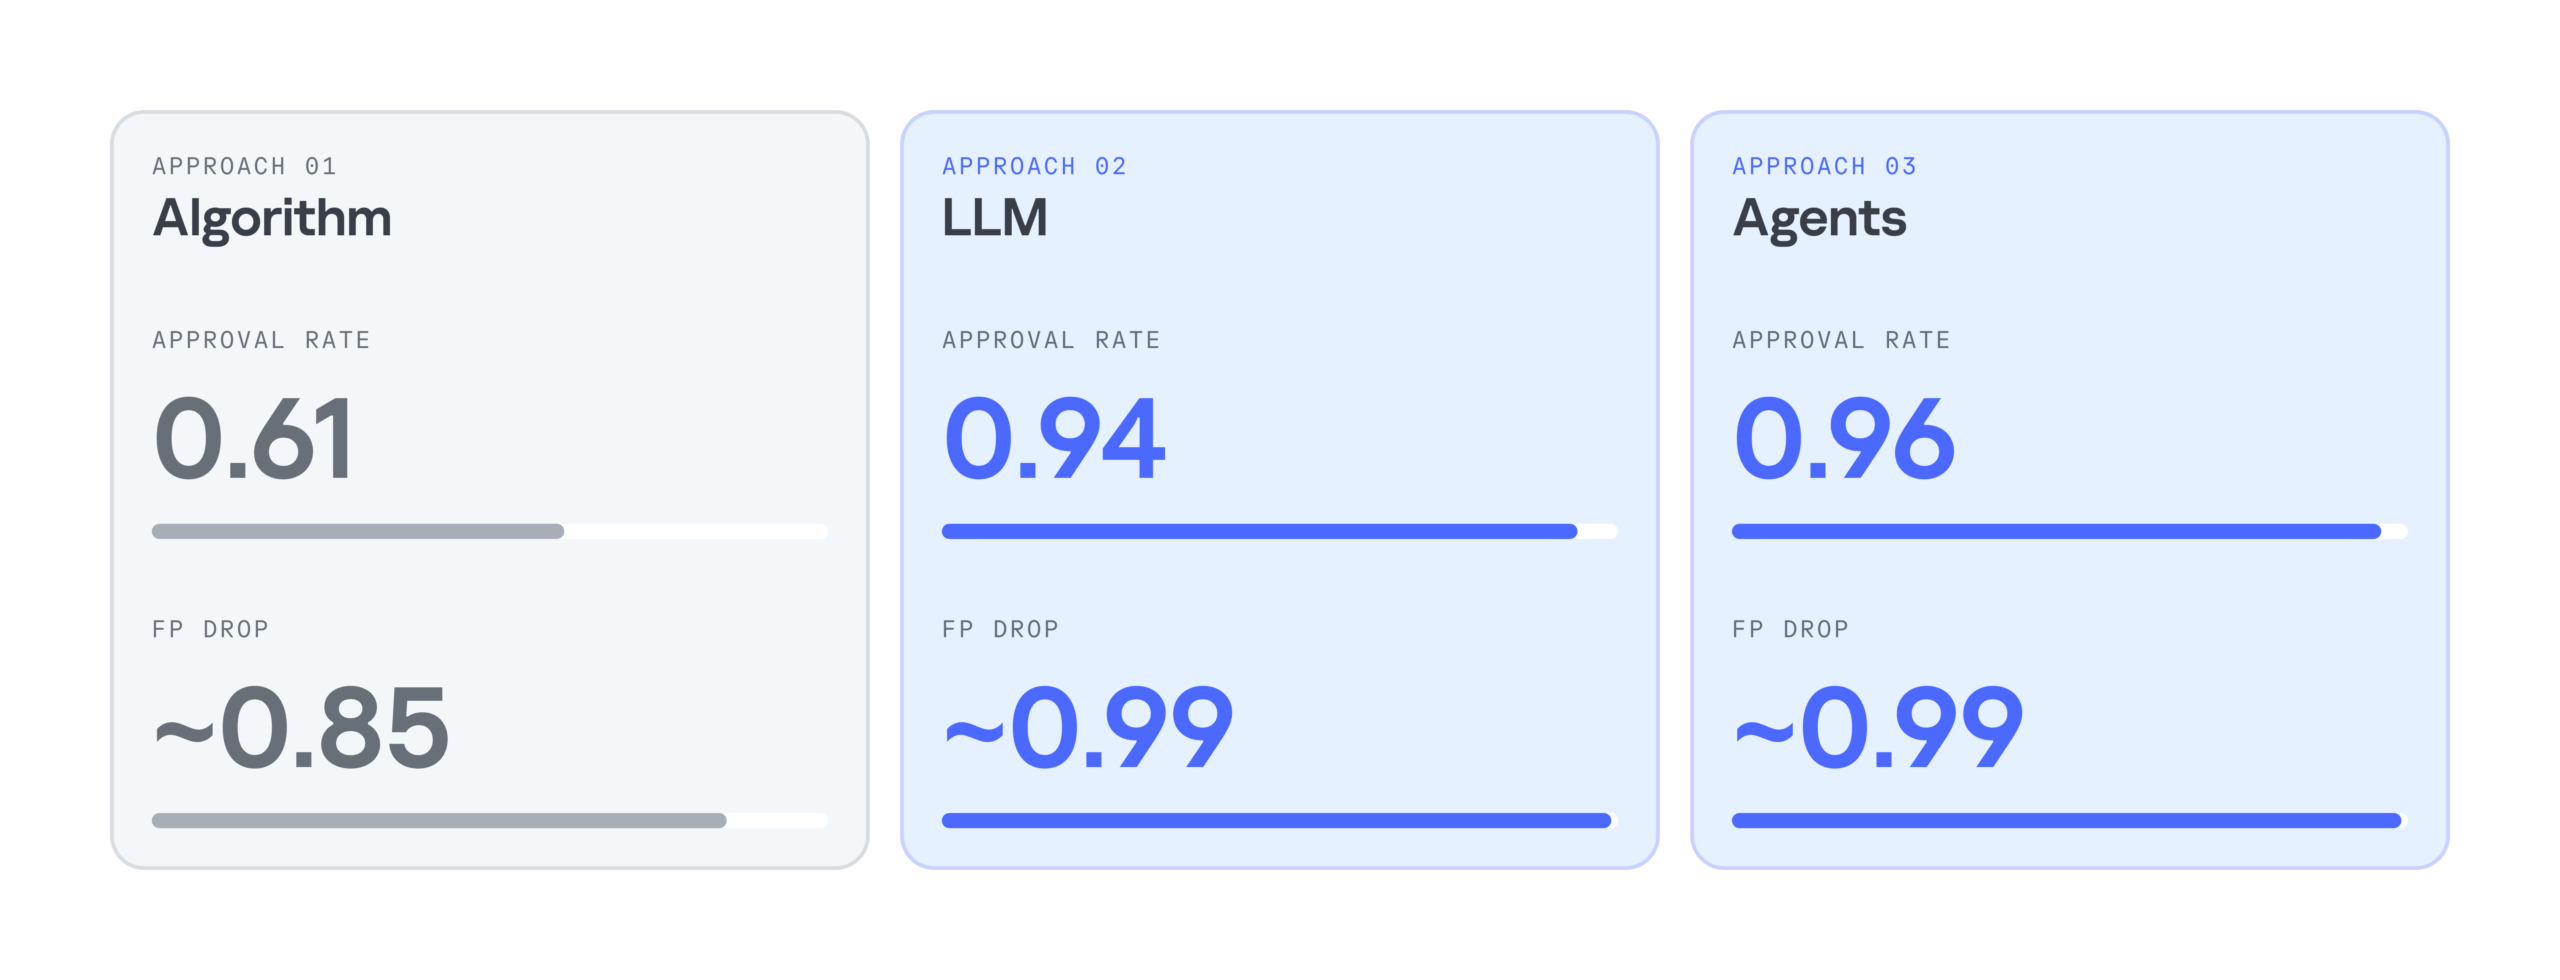
Below is a comparison of the three filter generation approaches by these metrics:
As the results show, LLMs significantly improve the efficiency of filter generation. At the same time, the LLM agentless and agent-based approaches perform almost identically. So we chose the simpler and faster option: an LLM with a single system prompt. As a result, we cut false positives by 99%, increased the number of filters generated per day by 28%, and made analysts’ alert handling 17% more efficient.
TakeawaysPractice has shown that filter generation can be automated effectively. We’ve looked at several options for automatically generating filters for false-positive security alerts: a purely algorithmic approach, an LLM-based approach, and an approach built on a group of LLM agents. All of them can generate valid filters and make the analyst’s work much easier, but each has its own pros and cons.
The algorithmic approach scored lower on the evaluation metrics, but in two-thirds of cases, it still produces filters that satisfy the analyst. It works especially well when there’s already a set of similar events to filter out, meaning enough context has accumulated. The algorithmic generator can also be deployed in any environment. Both standalone LLM and multi-agent LLM approaches show high accuracy, and their results differ only slightly, so the slower agent-based approach looks excessive at this stage. If an LLM is available, the best option appears to be a single model that handles several stages of the generation cycle.
Kategorie: Hacking & Security, Viry a Červi
Největší kryptokrádež v historii. Z Binance zmizelo 6,3 miliardy dolarů a stopy vedou do Severní Koreje
Kryptoburza Binance přiznala útok, škodu odhaduje zhruba na 6,3 miliardy dolarů. • Jde o největší krádež kryptoměn v historii, čtyřikrát větší než Bybit. • Analytici podezírají severokorejskou skupinu TraderTraitor ze sítě Lazarus.
Kategorie: IT News
Binance links $6.3 billion crypto theft to compromised DevOps laptop
Binance, the world's largest crypto exchange, has linked the theft of about $6.3 billion in cryptocurrency to a DevOps engineer's compromised laptop. [...]
Kategorie: Hacking & Security
Týden na ScienceMag.cz: Testovali hranice toho, co je (a co není) možné s umělou inteligencí
Černá díra rotující téměř maximální rychlostí by se prý mohla rozpadnout. Nobelova cena za fyziku 2026: Od neutrin k černým dírám. Grafen odhaluje skryté excitony v organických polovodičích. Je ditellurid wolframu materiálem pro paměťové technologie příští generace?
Kategorie: GNU/Linux & BSD
Meta bude hlavním zákazníkem Epyc Zen 6, rozšiřuje spolupráci s AMD
Společnost Meta je hlavním zákazníkem Epyců Venice, bude odebírat i příští generaci Verano a odebírá i nejnovější akcelerátory Instinct MI450, ke kterým přibude i semi-custom řešení postavené na míru…
Kategorie: IT News
Official Claude Code Extension on Cursor Marketplace Trojanized with Persistent SSH Backdoor
Cybersecurity researchers have disclosed that a trojanized version of Anthropic's official Claude Code extension was distributed through the Cursor Marketplace as a legitimate update, attempting to install a persistent SSH backdoor on affected systems.
The malicious update, version 2.1.313, was distributed under the extension's legitimate publisher identity, prompting Cursor to temporarily shutRavie Lakshmananhttp://www.blogger.com/profile/[email protected]
Kategorie: Hacking & Security
Insta360 má nové bezdrátové mikrofony. Zachrání i příliš hlasitou nahrávku a na displeji ukážou vaše logo
Insta360 rozšiřuje nabídku bezdrátových mikrofonů o model Mic. Přináší většinu funkcí dražšího Mic Pro, ale za nižší cenu. Má barevný displej s elektronickým inkoustem, umí záznam na paměťovou kartu a podporuje 32bitový float zvuk. Právě ten může zachránit nahrávky, u kterých kameraman špatně ...
Kategorie: IT News
Hackers Actively Exploit Highly Critical Drupal Commerce Core Authorization Bypass Flaw
Drupal has warned that threat actors are exploiting a "highly critical" security flaw in its Commerce Core component.
The vulnerability, tracked as CVE-2026-118539 (CVSS score: N/A), is a case of missing authorization affecting Commerce Core versions from 0.0.0 to 2.41 and from 3.0.0 to 3.3.13.
"This module enables you to sell goods and services to customers through an included shopping cart Ravie Lakshmananhttp://www.blogger.com/profile/[email protected]
Kategorie: Hacking & Security
CISA Adds Actively Exploited GitLab RCE and Cisco Firewall DoS Flaws to KEV
The U.S. Cybersecurity and Infrastructure Security Agency (CISA) on Thursday added two security flaws impacting Cisco and GitLab software to its Known Exploited Vulnerabilities (KEV), citing evidence of active exploitation.
The vulnerabilities are listed below -
CVE-2026-97229 (CVSS score: 10.0) - An integer overflow or wraparound vulnerability in GitLab Community Edition and Enterprise Ravie Lakshmananhttp://www.blogger.com/profile/[email protected]
Kategorie: Hacking & Security
NASA pořád neví, v čem bude za dva roky přistávat na Měsíci. Mění plán a udělala z toho souboj. Podívejte se na infografiku
Sice zatím stále nemáme jasno, v čem budou astronauti na misi Artemis IV přistávat na Měsíci, už ale víme jak.
NASA zveřejnila aktualizované infografiky letu k našemu sousedovi pomocí dvou zcela odlišných lunárních lodí. Příští rok se ukáže, která z nich opravdu funguje. A ta tam nakonec také ...
Kategorie: IT News
Z GeForce RTX 5080 je druhá RTX 5090, ceny vyletěly na ~$2500-$6000
Za ceny, které ještě před pár měsíci stála GeForce RTX 5090, už dnes pořídíte pouze GeForce RTX 5080. Nikoli novou 24GB, ale tu původní 16GB verzi…
Kategorie: IT News
- « první
- ‹ předchozí
- …
- 8
- 9
- 10
- 11
- 12
- 13
- 14
- 15
- 16
- …
- následující ›
- poslední »